NVIDIA DGX B200 Price, Specifications & Lead Time
A procurement-focused guide to NVIDIA DGX B200, an integrated Blackwell AI system engineered for large-scale model training, advanced inference and enterprise AI infrastructure.
A Full-Stack Blackwell Platform for the AI Factory
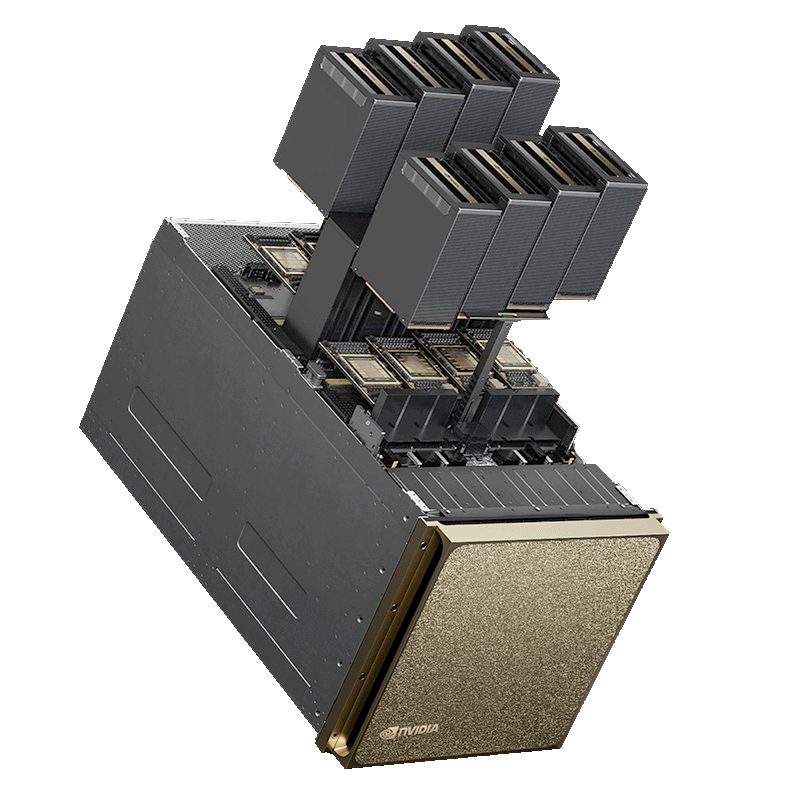
NVIDIA DGX B200 is an integrated AI platform built around eight NVIDIA Blackwell B200 GPUs connected through fifth-generation NVLink and NVIDIA NVSwitch technology. It combines GPU compute, CPU resources, high-speed networking, storage and NVIDIA AI software in a single 10U rackmount system.
The platform is designed to support the full AI lifecycle, from data preparation and model development to large-scale training, fine-tuning and production inference. Its integrated design can simplify deployment planning compared with assembling a multi-GPU infrastructure from separate components.
NVIDIA DGX B200 Technical Specifications
The following summary is based on NVIDIA's published DGX B200 product specifications and system documentation.
| GPU architecture | NVIDIA Blackwell |
|---|---|
| GPUs | 8 × NVIDIA B200 Tensor Core GPUs |
| Total GPU memory | 1,440GB HBM3e |
| GPU memory bandwidth | 64 TB/s aggregate |
| FP4 Tensor Core performance | Up to 144 PFLOPS sparse / 72 PFLOPS dense |
| FP8 Tensor Core performance | Up to 72 PFLOPS sparse |
| NVLink / NVSwitch | Fifth-generation NVLink; 2 × NVSwitch |
| Aggregate NVLink bandwidth | 14.4 TB/s |
| CPU | 2 × Intel Xeon Platinum 8570 processors; 112 cores total |
| System memory | 2TB, configurable up to 4TB |
| Cluster networking | 4 × OSFP ports serving 8 × single-port NVIDIA ConnectX-7 VPI; up to 400Gb/s per adapter |
| DPU | 2 × dual-port NVIDIA BlueField-3 DPU |
| OS storage | 2 × 1.92TB NVMe M.2 SSD in RAID 1 |
| Internal data storage | 8 × 3.84TB NVMe U.2 SSD in RAID 0 |
| Maximum system power | Approximately 14.3kW |
| Form factor | 10U rackmount |
| Dimensions (H × W × D) | 444 × 482.2 × 897.1mm |
| Operating temperature | 10–35°C (50–90°F) |
| Enterprise support | Three-year Enterprise Business-Standard support for hardware and software, subject to the purchased support entitlement |
DGX B200 Performance for Training and Inference
Large-Scale AI Training
Eight Blackwell GPUs and high-bandwidth NVLink connectivity provide a tightly coupled compute platform for training and fine-tuning large AI models, including large language models and multimodal workloads.
Generative AI Inference
The system is designed to serve demanding inference workloads, including conversational AI, retrieval-augmented generation and high-throughput model serving.
Recommendation Systems
GPU acceleration and high-speed interconnects can support large recommendation models and data-intensive machine-learning pipelines.
Scientific Computing
DGX B200 can also support accelerated analytics, simulation and other high-performance computing applications that are optimized for NVIDIA GPUs.
Real-world throughput depends on model architecture, precision, batch size, software optimization, data pipeline and cluster configuration. Published peak figures should not be interpreted as guaranteed application performance.
1.44TB of HBM3e GPU Memory and Fifth-Generation NVLink
Across its eight B200 GPUs, DGX B200 provides 1,440GB of total HBM3e GPU memory. This large aggregate memory capacity is intended for demanding AI workloads and models that require substantial GPU-resident working data.
Fifth-generation NVLink and two NVIDIA NVSwitch components provide up to 14.4 TB/s of aggregate NVLink bandwidth within the system. This high-speed GPU fabric supports communication among the eight GPUs during distributed training and other multi-GPU workloads.
High-Speed Networking, DPU and NVMe Storage
DGX B200 integrates high-speed networking for scale-out AI infrastructure. Four OSFP ports serve eight single-port NVIDIA ConnectX-7 VPI adapters, supporting InfiniBand or Ethernet connectivity at speeds up to 400Gb/s per adapter, depending on configuration.
Two dual-port NVIDIA BlueField-3 DPUs provide additional connectivity for storage and in-band management. For local storage, the system includes two 1.92TB NVMe M.2 drives in a RAID 1 operating-system array and eight 3.84TB NVMe U.2 drives in a RAID 0 data-cache array.
Power, Rack Space and Deployment Planning
Because DGX B200 is a high-density 10U AI system, procurement planning should include a site-readiness review before delivery and installation. The maximum system power usage is approximately 14.3kW, so facility power distribution, redundancy and cooling capacity must be assessed by qualified data-center personnel.
- Rack capacity: reserve 10U of compatible rack space and verify depth, rails, service clearance and floor loading.
- Electrical infrastructure: confirm the required power feeds, connectors, distribution units and redundancy design with NVIDIA documentation and the site team.
- Cooling: validate the data-center cooling design and environmental operating conditions for the system's heat output.
- Network fabric: plan InfiniBand or Ethernet switching, transceivers, cabling and cluster topology.
- Operations: plan secure management access, monitoring, software lifecycle and enterprise support coverage.
- Logistics: account for system dimensions, weight, delivery access and handling requirements.
NVIDIA DGX B200 Price
The NVIDIA DGX B200 price is quotation-based and may vary according to regional supply, configuration, purchase quantity, support entitlement, delivery destination and applicable logistics or import costs. Enterprise procurement may also include networking, rack integration, deployment services and support requirements.
For an accurate quotation, share the required quantity, destination country, target delivery schedule and any preferred support or infrastructure options. Sadid Gostaran can help coordinate a procurement enquiry based on your project requirements.
DGX B200 Availability and Lead Time
Availability and delivery lead time are confirmed at the time of quotation. They can be affected by allocation, order volume, destination, shipping arrangements, export-control screening and the requested support or deployment scope.
To receive a useful estimate, provide your required quantity, delivery destination and target delivery date. Any indicative schedule remains subject to written confirmation and current supply conditions.
NVIDIA DGX B200 vs Previous-Generation DGX Systems
DGX B200 introduces the Blackwell architecture, fifth-generation NVLink and a larger aggregate GPU memory configuration compared with the previous DGX H100 generation.
| GPU platform | DGX B200: 8 × NVIDIA Blackwell B200 GPUs |
|---|---|
| GPU memory | DGX B200: 1,440GB total HBM3e |
| GPU interconnect | DGX B200: fifth-generation NVLink and NVSwitch |
| Aggregate NVLink bandwidth | DGX B200: 14.4 TB/s |
| Intended use | Both generations support enterprise AI; DGX B200 targets newer, larger-scale Blackwell training and inference workloads. |
A fair platform comparison should consider the target model, precision, inference latency, training throughput, power envelope, software compatibility and total cost of ownership—not only peak FLOPS.
Frequently Asked Questions
How many GPUs are included in NVIDIA DGX B200?
DGX B200 includes eight NVIDIA Blackwell B200 Tensor Core GPUs.
How much total GPU memory does DGX B200 provide?
The system provides 1,440GB of total HBM3e GPU memory across its eight GPUs.
What is the DGX B200 NVLink bandwidth?
NVIDIA lists 14.4 TB/s of aggregate NVLink bandwidth using fifth-generation NVLink and NVSwitch.
What is the maximum power usage of DGX B200?
NVIDIA lists approximately 14.3kW maximum system power usage. Facility requirements must be checked against the official documentation and site design.
How much rack space does DGX B200 require?
The system is a 10U rackmount platform. Rack depth, weight, power and cooling requirements must also be checked.
Can I request a price and delivery estimate?
Yes. Contact Sadid Gostaran with your required quantity and delivery destination to request current pricing, availability and lead-time information.
Request a Quotation for NVIDIA DGX B200
Contact our team for current pricing, supply status, delivery lead time and enterprise procurement enquiries.
Chat with Sales on WhatsApp ↗WhatsApp: +98 912 427 1734
Available in Iran
Looking for the NVIDIA DGX B200 product page for the Iranian market? Visit the Persian product page for local product information and purchasing options.
View Persian Product PageExplore more: NVIDIA product directory · AI infrastructure in Iran