NVIDIA H100 NVL 94GB PCIe: Price, Technical Specifications & Availability
A procurement-focused guide to NVIDIA H100 NVL for enterprise AI and accelerated computing, covering 94GB HBM3 memory, performance, PCIe Gen5, NVLink connectivity, server requirements, pricing and supply planning.
Pricing, exact SKU, paired-GPU configuration and lead time are confirmed individually against current supply.
Executive Summary
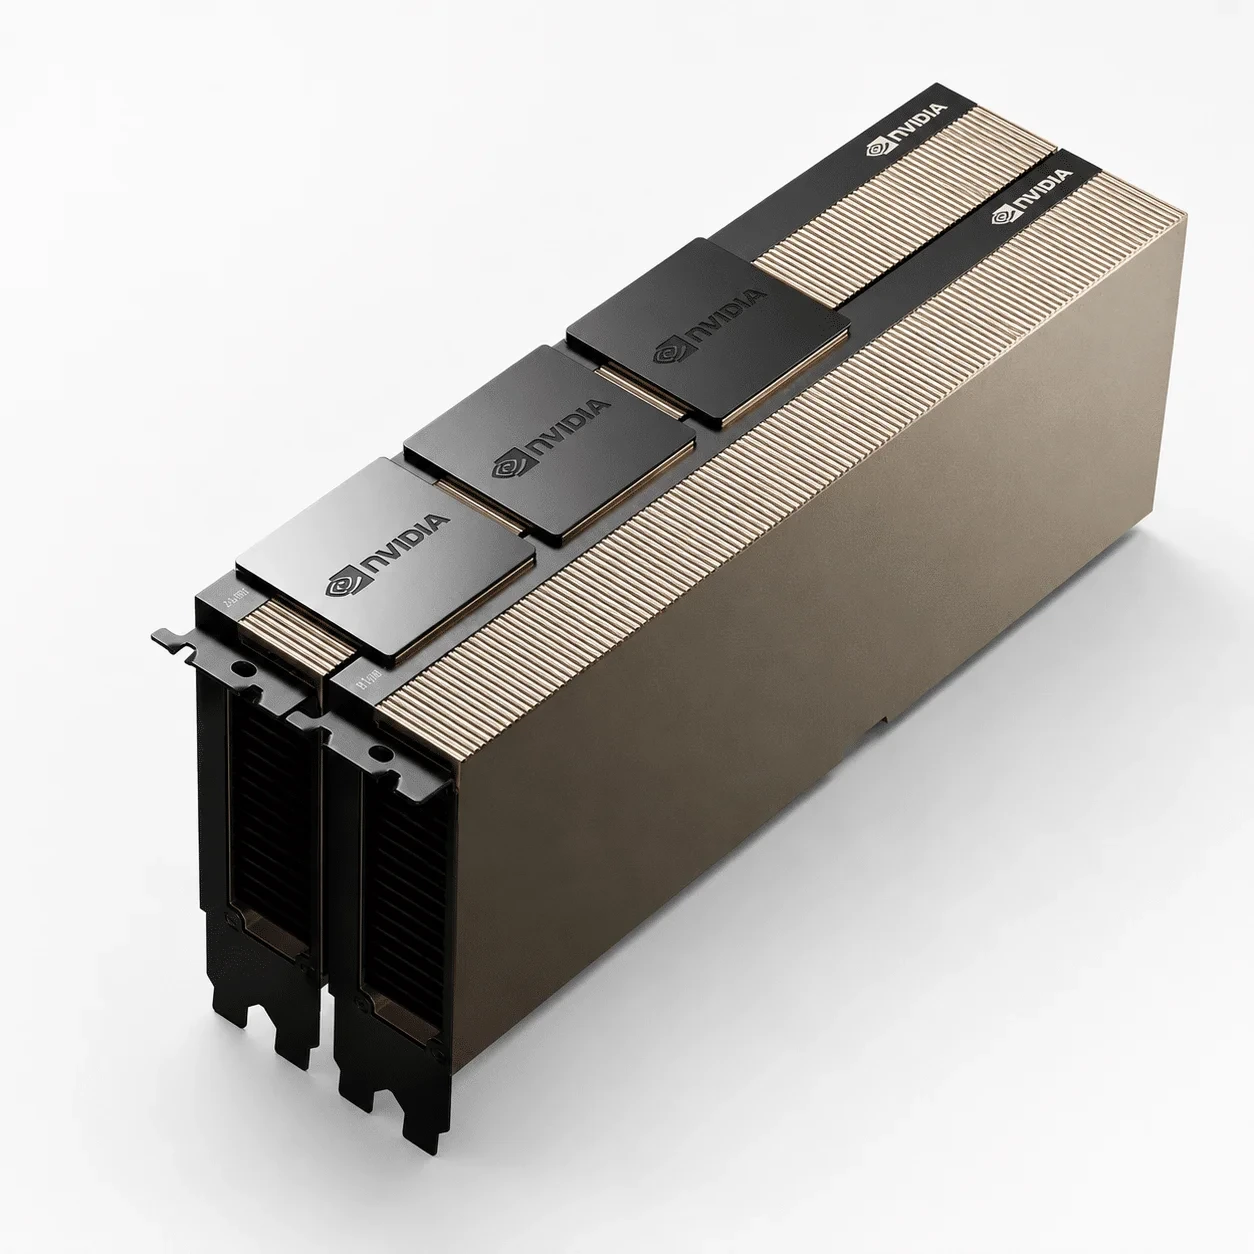
The NVIDIA H100 NVL is a data-center GPU accelerator based on the Hopper architecture and designed for large language model (LLM) inference, enterprise AI and accelerated computing in PCIe-based server platforms. Each H100 NVL GPU provides 94GB of HBM3 memory and up to 3.9 TB/s of memory bandwidth.
H100 NVL is particularly notable for its NVLink capability. Two compatible H100 NVL cards can be connected as a paired configuration using the required NVLink bridges, providing 188GB of aggregate GPU memory across the two devices. This is a two-GPU configuration, not 188GB on a single card.
What Is NVIDIA H100 NVL 94GB PCIe?
H100 NVL is designed to bring high-performance AI acceleration to mainstream PCIe server systems. It combines Hopper Tensor Core technology, high-bandwidth HBM3 memory and NVLink connectivity to support demanding generative AI and data-center workloads.
The NVL designation matters: buyers should not confuse H100 NVL 94GB with the standard H100 PCIe 80GB or H100 SXM variants. These configurations differ in memory capacity, bandwidth, power envelope, physical implementation and interconnect options.
NVIDIA H100 NVL 94GB Price
NVIDIA does not publish a universal retail price for every H100 NVL procurement route. Final pricing can vary by supplier, exact part number, order quantity, warranty, server qualification, NVLink bridge requirements, region and delivery destination.
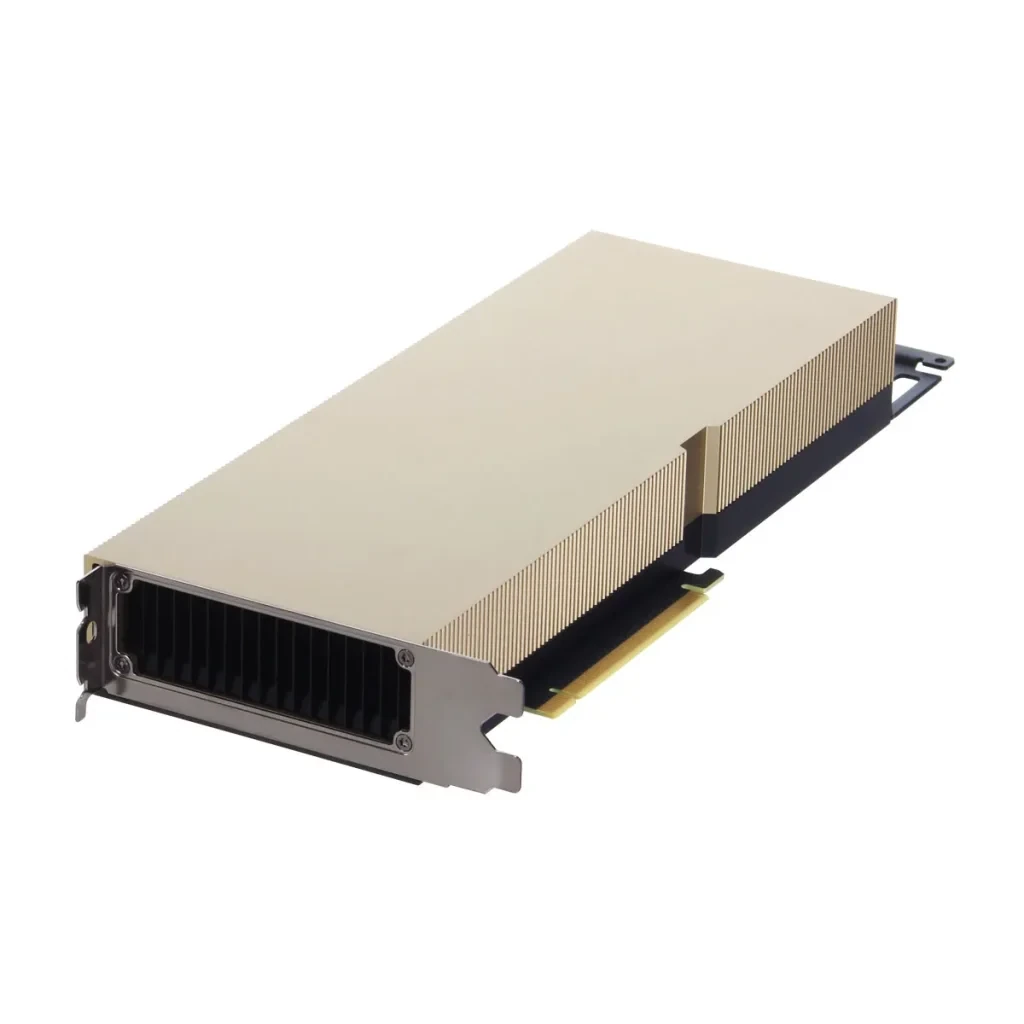
When requesting a quotation, specify whether you need one 94GB accelerator or a two-card NVLink-connected configuration. This distinction affects the bill of materials, system compatibility and total procurement cost.
Send the required quantity, destination country and whether the order is for a single card or an NVLink pair.
Get Price via WhatsApp ↗NVIDIA H100 NVL 94GB PCIe Technical Specifications
The table below summarizes the published H100 NVL specifications. Values stated per GPU are distinguished from paired-system aggregate values.
| Specification | H100 NVL (per GPU) |
|---|---|
| GPU architecture | NVIDIA Hopper |
| GPU memory | 94GB HBM3 |
| Memory bandwidth | 3.9 TB/s |
| FP64 performance | 30 TFLOPS |
| FP64 Tensor Core | 60 TFLOPS |
| FP32 performance | 60 TFLOPS |
| TF32 Tensor Core | 835 TFLOPS* |
| BF16 / FP16 Tensor Core | 1,671 TFLOPS* |
| FP8 Tensor Core | 3,341 TFLOPS* |
| INT8 Tensor Core | 3,341 TOPS* |
| System interface | PCI Express Gen5 x16 |
| GPU interconnect | NVIDIA NVLink, up to 600 GB/s |
| Power envelope | 350–400W configurable |
| Form factor | PCIe, dual-slot, air-cooled |
| Multi-Instance GPU | Up to 7 MIG instances of 12GB each |
*Tensor Core figures are published with sparsity. Confirm the exact board, power limit, server support and cooling requirements with the supplier and system manufacturer before purchase. Paired H100 NVL configurations use two GPUs; aggregate figures must not be mistaken for per-card specifications.
NVIDIA H100 NVL product specifications ↗ | PNY H100 NVL product page ↗
94GB HBM3 Memory and 3.9 TB/s Bandwidth
Each H100 NVL accelerator is equipped with 94GB of HBM3 memory and up to 3.9 TB/s of memory bandwidth. High-bandwidth memory is central to workloads that repeatedly move large tensors and model parameters through the GPU, including LLM inference and other data-intensive AI tasks.
For a two-GPU NVLink pair, the aggregate installed GPU memory is 188GB. This does not automatically behave as one unified memory pool for every application: software, model parallelism, framework support and workload partitioning determine how the two GPUs use their memory.
One H100 NVL card provides 94GB. Two H100 NVL cards connected with the supported NVLink bridge configuration provide 188GB aggregate GPU memory.
NVIDIA Hopper Architecture and Tensor Core Acceleration
Hopper introduced architectural features designed to accelerate AI and high-performance computing. H100 NVL uses Tensor Core capabilities and the Transformer Engine to accelerate supported transformer-based workloads and mixed-precision operations.
Transformer Engine
The Transformer Engine uses supported precision formats, including FP8 and FP16, to improve the efficiency of transformer model workloads. Actual throughput depends on the model, framework, software stack and precision configuration.
Confidential computing and enterprise operation
H100 platform capabilities include hardware-supported security features for protecting data and applications in supported configurations. Enterprise deployment should validate firmware, driver, virtualization and server-vendor support.
H100 NVL NVLink: Connecting Two GPUs
H100 NVL supports NVIDIA NVLink connectivity. In a supported two-card configuration, NVLink bridges connect the GPUs to provide high-bandwidth GPU-to-GPU communication for workloads that are distributed across devices.
- One GPU: 94GB HBM3 memory on a single H100 NVL card.
- Two-GPU pair: 188GB aggregate installed HBM3 memory across two cards.
- NVLink: Up to 600GB/s interconnect bandwidth per GPU as specified by NVIDIA.
- Bridge hardware: The appropriate NVLink bridge set and physical spacing must be supported by the server platform.
NVLink is not Ethernet and does not connect the GPU to a conventional network switch. It is a GPU-to-GPU interconnect. Server chassis, slot spacing, bridge availability and supported GPU topology must be confirmed before procurement.
H100 NVL for LLM Inference and Generative AI
H100 NVL is designed for demanding generative AI inference in PCIe-based server systems. Its 94GB of HBM3 memory per GPU and high memory bandwidth can support large model deployments, subject to model size, precision, context length, batching and software configuration.
- Large language model inference and serving.
- Generative AI applications and enterprise copilots.
- Retrieval-augmented generation (RAG) pipelines.
- Speech AI, computer vision and multimodal inference.
- AI development and accelerated data processing.
For larger models, multiple GPUs may be required. The usable model capacity and performance depend on quantization, runtime, parallelization strategy, KV-cache requirements and the memory available to each process.
HPC, Scientific Computing and Enterprise Workloads
Beyond generative AI, H100 NVL can accelerate compatible high-performance computing and data-center applications. Hopper’s compute and memory capabilities are relevant to workloads that benefit from parallel processing and GPU acceleration.
Scientific and technical computing
Supported CUDA applications can use H100 NVL for numerical workloads, simulation, analytics and data processing. Performance varies with algorithm design, precision and data movement.
Enterprise AI infrastructure
Organizations can deploy H100 NVL in qualified PCIe servers as part of an AI infrastructure strategy. The correct number of GPUs depends on throughput targets, concurrency, model size and service-level requirements.
Server Compatibility and Deployment Requirements
H100 NVL is a server accelerator, not a standard desktop graphics card. Before purchase, verify that the server vendor supports the exact GPU model and intended number of accelerators.
- Platform qualification: Confirm the server model and GPU enablement kit support H100 NVL.
- PCIe: Validate PCIe Gen5 x16 slot availability, lane allocation and BIOS/firmware support.
- Power: Allow for the configurable 350–400W GPU power envelope and the manufacturer-specified auxiliary power connection.
- Cooling: The H100 NVL is a dual-slot, air-cooled PCIe accelerator; server airflow must meet the GPU vendor’s requirements.
- NVLink pair: Check slot spacing, bridge kit and server compatibility if two GPUs are to be linked.
- Software: Validate CUDA, drivers, operating system, virtualization and AI framework versions.
Do not size a server PSU from GPU TDP alone. CPU, memory, storage, fans, other accelerators, transient loads and the server manufacturer’s approved configuration all affect system power requirements.
H100 NVL 94GB vs H100 PCIe 80GB
H100 NVL and standard H100 PCIe are distinct configurations. The H100 NVL offers 94GB HBM3 memory, higher memory bandwidth and NVLink support. Standard H100 PCIe is an 80GB configuration with different memory and interconnect specifications.
| Specification | H100 NVL | H100 PCIe |
|---|---|---|
| GPU memory | 94GB HBM3 | 80GB |
| Memory bandwidth | 3.9 TB/s | 2.0 TB/s |
| Form factor | PCIe dual-slot, air-cooled | PCIe dual-slot, air-cooled |
| Power envelope | 350–400W configurable | 300–350W configurable |
| NVLink | Supported, 600GB/s | Supported, 600GB/s |
| PCIe interface | Gen5 x16 | Gen5 x16 |
Specifications are summarized from NVIDIA’s H100 datasheet. Confirm the exact revision and server implementation before comparing quotations.
NVIDIA H100 NVL 94GB Availability and Lead Time
Availability depends on the exact accelerator SKU, regional distribution, order quantity, server qualification and delivery destination. For an NVLink pair, the availability of the second GPU and the required bridge hardware should be confirmed together.
Sadid Gostaran can check the current supply position and provide a quotation based on the requested configuration. Lead time is confirmed individually rather than assumed from general market announcements.
Tell us whether you need one GPU or a two-card NVLink pair, plus the required quantity and destination.
Check Availability via WhatsApp ↗NVIDIA H100 NVL 94GB PCIe FAQs
How much memory does one H100 NVL GPU have?
Each H100 NVL GPU provides 94GB of HBM3 memory.
Does one H100 NVL card provide 188GB of memory?
No. One card provides 94GB. The 188GB figure refers to the aggregate memory of a supported two-GPU NVLink pair.
What is the H100 NVL memory bandwidth?
NVIDIA specifies up to 3.9 TB/s per GPU.
Does H100 NVL support NVLink?
Yes. H100 NVL supports NVIDIA NVLink at up to 600GB/s. A compatible bridge configuration is required to connect a pair of cards.
What is the power requirement?
The published configurable power range is 350–400W per GPU. Check the exact card and server vendor requirements for auxiliary power, cooling and PSU sizing.
Is H100 NVL compatible with any PCIe server?
No. The server must be qualified for the exact GPU, its power and cooling requirements, and the intended one- or two-GPU topology.
What workloads is H100 NVL designed for?
It is designed for enterprise AI, large language model inference, generative AI and other accelerated computing workloads.
How can I request a price and lead time?
Contact Sadid Gostaran via WhatsApp with the required quantity, destination and whether you need a single GPU or an NVLink pair.
Is NVIDIA H100 NVL 94GB PCIe Right for Your AI Server?
NVIDIA H100 NVL combines Hopper architecture, 94GB of HBM3 memory per GPU, 3.9 TB/s memory bandwidth and NVLink connectivity in a PCIe-based data-center accelerator. It is a strong option to evaluate for enterprise AI and LLM inference deployments that need high memory capacity and a supported path to two-GPU NVLink configurations.
The final choice should be based on workload requirements, server qualification, power and cooling, exact SKU, bridge hardware and confirmed supply. Contact Sadid Gostaran for a configuration-specific quotation.
Request an NVIDIA H100 NVL Quotation
Ask about the 94GB PCIe accelerator, single-GPU or NVLink-pair configuration, availability, warranty and delivery options.
+98 912 427 1734MESSAGE ON WHATSAPP ↗ WhatsApp inquiries only · Sadid GostaranAvailable in Iran
Looking for the NVIDIA H100 NVL 94GB PCIe product page for the Iranian market? Visit the Persian product page for local product information and purchasing options.
View Persian Product PageExplore more: NVIDIA product directory · AI infrastructure in Iran