NVIDIA H200 NVL 141GB PCIe: Price, Technical Specifications & Availability
A procurement-focused guide to NVIDIA H200 NVL for enterprise AI and accelerated computing, covering 141GB HBM3e memory, 4.8 TB/s bandwidth, NVLink connectivity, PCIe Gen5, server requirements, pricing and lead times.
Pricing, exact SKU, server qualification and lead time are confirmed individually against current supply.
Executive Summary
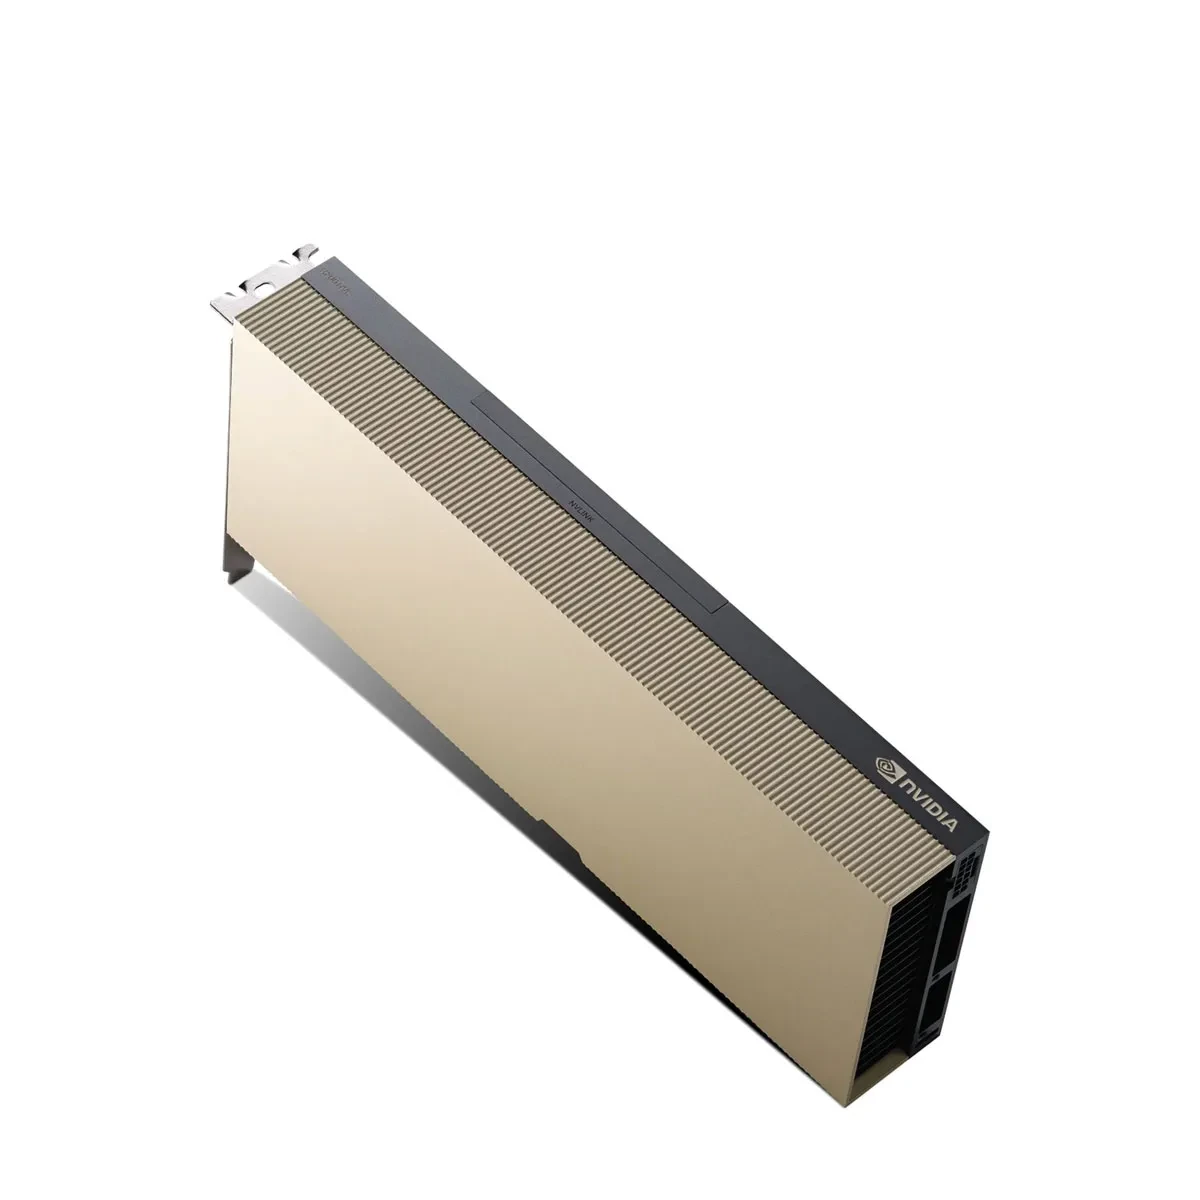
The NVIDIA H200 NVL is a PCIe data-center GPU accelerator based on the Hopper architecture. It is designed for generative AI, large language model (LLM) inference, high-performance computing (HPC) and enterprise accelerated computing.
Each H200 NVL card provides 141GB of HBM3e memory and up to 4.8 TB/s of memory bandwidth. Compared with the H100 generation, the larger and faster memory capacity is particularly relevant to memory-intensive AI workloads and larger model deployments.
H200 NVL supports two-way or four-way NVLink bridge configurations, subject to compatible server layouts and required bridge hardware. The published NVLink bandwidth is up to 900GB/s per GPU.
What Is NVIDIA H200 NVL 141GB PCIe?
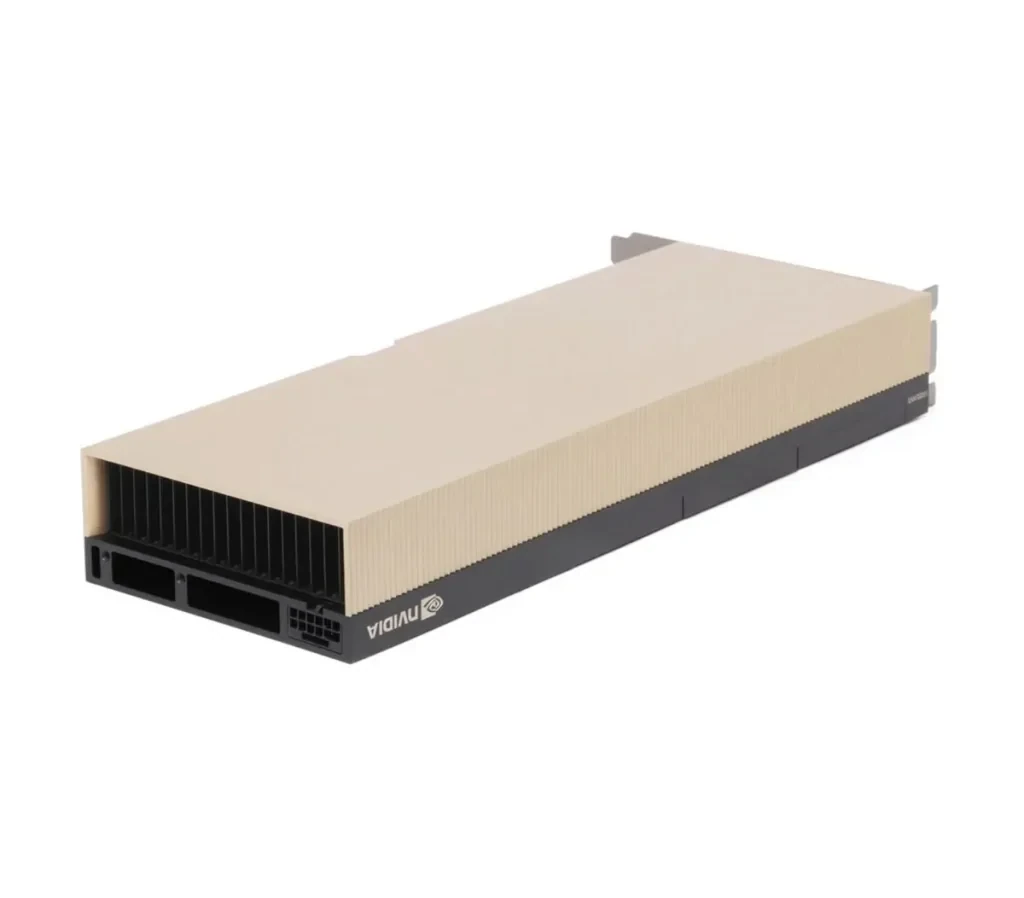
H200 NVL brings NVIDIA Hopper Tensor Core GPU capabilities to PCIe-based server platforms. Its dual-slot, air-cooled form factor is intended for qualified enterprise servers, including selected NVIDIA MGX and NVIDIA-Certified Systems.
The H200 NVL should not be confused with the H200 SXM module. Although both use the Hopper architecture and 141GB HBM3e memory, their form factors, power envelopes, platform requirements and interconnect implementation differ.
NVIDIA H200 NVL 141GB PCIe Price
NVIDIA does not provide one universal public retail price for every H200 NVL purchasing route. Actual quotations depend on supplier, exact part number, order quantity, regional availability, warranty, destination and whether the GPU is purchased as a standalone accelerator or as part of a qualified server configuration.
For multi-GPU deployments, specify whether you require a two-way or four-way NVLink configuration. The required bridge kit, supported chassis layout and server qualification can affect the total bill of materials.
Send your required quantity, destination country and whether you need a single GPU or an NVLink-connected configuration.
Get Price via WhatsApp ↗NVIDIA H200 NVL 141GB PCIe Technical Specifications
The following values summarize the published H200 NVL PCIe specifications. Tensor Core performance figures marked with an asterisk use sparsity.
| Specification | NVIDIA H200 NVL PCIe |
|---|---|
| GPU architecture | NVIDIA Hopper |
| GPU memory | 141GB HBM3e |
| Memory bandwidth | 4.8 TB/s |
| FP64 performance | 30 TFLOPS |
| FP64 Tensor Core | 60 TFLOPS |
| FP32 performance | 60 TFLOPS |
| TF32 Tensor Core | 835 TFLOPS* |
| BF16 / FP16 Tensor Core | 1,671 TFLOPS* |
| FP8 Tensor Core | 3,341 TFLOPS* |
| INT8 Tensor Core | 3,341 TOPS* |
| System interface | PCI Express Gen5 x16 |
| PCIe bandwidth | 128 GB/s |
| GPU interconnect | 2-way or 4-way NVIDIA NVLink bridge |
| NVLink bandwidth | Up to 900 GB/s per GPU |
| Maximum TDP | Up to 600W, configurable |
| Form factor | PCIe, dual-slot, air-cooled |
| Multi-Instance GPU | Up to 7 MIG instances, 16.5GB each |
| Server options | Qualified NVIDIA MGX H200 NVL and NVIDIA-Certified Systems |
| NVIDIA AI Enterprise | Included with H200 NVL |
*With sparsity. Specifications are based on manufacturer documentation and may be subject to revision. Confirm exact board SKU and system qualification before ordering.
NVIDIA H200 official specifications ↗ | PNY H200 NVL product specifications ↗
141GB HBM3e Memory and 4.8 TB/s Bandwidth
Each H200 NVL GPU is equipped with 141GB of HBM3e memory and up to 4.8 TB/s of memory bandwidth. This high-capacity memory subsystem is designed to reduce memory constraints in demanding AI and HPC workloads.
For LLM inference, additional GPU memory can accommodate larger model weights, longer context windows, larger KV caches or higher concurrency, depending on the model architecture, precision, runtime and serving strategy.
The 141GB specification refers to one H200 NVL card. Multi-GPU configurations provide multiple GPU memory spaces; application software and parallelization determine how those resources are used.
NVIDIA Hopper Architecture and Tensor Core Acceleration
H200 NVL is built on NVIDIA Hopper and uses Tensor Core technology to accelerate supported AI and HPC operations. Its Transformer Engine supports precision formats such as FP8 and FP16 for transformer workloads, helping improve throughput and memory efficiency where supported by the software stack.
Transformer Engine
The Transformer Engine dynamically uses supported precision formats to accelerate transformer model computation. Real-world performance depends on model design, framework, precision settings, batch size and software optimization.
Confidential Computing
H200 NVL supports NVIDIA confidential computing capabilities in supported configurations. Organizations should validate the relevant server firmware, drivers, virtualization stack and deployment architecture.
H200 NVL NVLink: Two-Way and Four-Way GPU Connectivity
H200 NVL supports two-way and four-way NVLink bridge configurations. NVLink provides high-bandwidth communication between compatible GPUs and can help scale workloads that distribute model computation or data across multiple accelerators.
- Single GPU: One H200 NVL card with 141GB HBM3e memory.
- Two-way configuration: Two compatible GPUs connected using the required two-way NVLink bridge kit.
- Four-way configuration: Four compatible GPUs connected using the required four-way NVLink bridge kit.
- NVLink bandwidth: Up to 900GB/s per GPU as published for H200 NVL.
NVLink is a GPU-to-GPU interconnect, not Ethernet and not a connection to a conventional network switch. Bridge compatibility, card spacing, chassis support and GPU topology must be checked before purchase.
H200 NVL for LLM Inference and Generative AI
The 141GB HBM3e memory capacity makes H200 NVL relevant to memory-intensive generative AI inference and enterprise model-serving workloads. Depending on model size and configuration, the larger memory pool per GPU can reduce the need to shard a model across as many devices.
- Large language model inference and serving.
- Generative AI applications and enterprise copilots.
- Retrieval-augmented generation (RAG) pipelines.
- Multimodal AI, speech and computer vision workloads.
- High-throughput inference and model experimentation.
Model fit and serving performance depend on parameter count, quantization, context length, KV-cache size, batch size and runtime. GPU memory capacity alone does not guarantee a particular model throughput or latency.
HPC, Scientific Computing and Enterprise Workloads
H200 NVL can accelerate CUDA-enabled scientific and enterprise applications that benefit from parallel computation and high-bandwidth GPU memory.
Scientific computing
Potential workloads include simulation, numerical analysis, computational science and data-intensive research. Application-level performance depends on algorithm design, data movement and precision requirements.
Enterprise data centers
Qualified PCIe servers equipped with H200 NVL can support AI inference, analytics and accelerated workloads. The required GPU count should be determined from throughput, concurrency, latency and availability targets.
H200 NVL Server Compatibility and Deployment Requirements
H200 NVL is a high-power data-center accelerator. It is not a general-purpose desktop graphics card and should only be installed in server platforms qualified for the exact GPU and intended topology.
- Platform qualification: Confirm the server vendor supports H200 NVL and the required number of GPUs.
- PCIe interface: Verify PCIe Gen5 x16 slot availability and lane allocation.
- Power delivery: Plan for up to 600W configurable GPU power and the exact auxiliary power connector specified for the board.
- Cooling: Confirm dual-slot air-cooled GPU support and sufficient chassis airflow.
- NVLink: Check bridge kit, slot spacing and approved two-way or four-way GPU layout.
- Software: Validate CUDA, drivers, operating system, virtualization and AI framework compatibility.
Do not size a server power supply from GPU TDP alone. CPU, memory, storage, fans, additional accelerators, transient loads and manufacturer-approved configurations also affect system power requirements.
NVIDIA H200 NVL vs H100 NVL
H200 NVL builds on the Hopper platform with a larger and faster HBM3e memory subsystem than H100 NVL. This difference is particularly relevant for workloads constrained by GPU memory capacity or bandwidth.
| Specification | H200 NVL | H100 NVL |
|---|---|---|
| GPU memory | 141GB HBM3e | 94GB HBM3 |
| Memory bandwidth | 4.8 TB/s | 3.9 TB/s |
| FP64 | 30 TFLOPS | 30 TFLOPS |
| FP32 | 60 TFLOPS | 60 TFLOPS |
| FP8 Tensor Core* | 3,341 TFLOPS | 3,341 TFLOPS |
| Maximum TDP | Up to 600W | Up to 400W |
| NVLink | Up to 900GB/s per GPU | Up to 600GB/s per GPU |
| PCIe interface | Gen5 x16 | Gen5 x16 |
*With sparsity. Confirm the exact SKU and manufacturer specification revision before using this table for procurement decisions. H200 NVL and H100 NVL power and interconnect figures are configuration-specific.
NVIDIA H200 NVL 141GB Availability and Lead Time
H200 NVL availability and delivery timelines depend on the exact part number, order quantity, supplier allocation, destination and server configuration. Multi-GPU orders may also require compatible NVLink bridge kits and a qualified chassis.
Sadid Gostaran can check current supply and provide a quotation based on the requested configuration. Stock status and lead time are confirmed individually rather than inferred from general product announcements.
Send your required quantity, destination and whether you need a single GPU, two-way or four-way NVLink configuration.
Check Availability via WhatsApp ↗NVIDIA H200 NVL 141GB PCIe FAQs
How much memory does one NVIDIA H200 NVL GPU have?
Each H200 NVL PCIe accelerator has 141GB of HBM3e memory.
What is the H200 NVL memory bandwidth?
NVIDIA specifies up to 4.8 TB/s of GPU memory bandwidth.
How much power does H200 NVL require?
Its maximum configurable TDP is up to 600W. The exact server power and cooling design must be validated with the system vendor.
Does H200 NVL support NVLink?
Yes. H200 NVL supports two-way and four-way NVLink bridge configurations, with up to 900GB/s bandwidth per GPU as specified by NVIDIA.
Is H200 NVL the same as H200 SXM?
No. H200 NVL is a dual-slot air-cooled PCIe card, while H200 SXM is a different module and platform configuration. Their power and system requirements differ.
Can H200 NVL be installed in any PCIe server?
No. The server must be qualified for the card's power, cooling, physical dimensions, PCIe topology and intended NVLink configuration.
What workloads benefit from H200 NVL?
H200 NVL is designed for generative AI, large language model inference, high-performance computing and other accelerated workloads.
How can I request a price and lead time?
Contact Sadid Gostaran via WhatsApp with your quantity, destination and single- or multi-GPU configuration requirements.
Is NVIDIA H200 NVL 141GB PCIe Right for Your AI Server?
NVIDIA H200 NVL combines Hopper architecture, 141GB of HBM3e memory, 4.8 TB/s bandwidth and PCIe Gen5 connectivity in a dual-slot, air-cooled data-center GPU. Its support for two-way and four-way NVLink configurations makes it a compelling option to evaluate for enterprise AI inference and memory-intensive accelerated computing.
The right configuration depends on workload size, GPU count, server qualification, power and cooling capacity, bridge hardware and confirmed supply. Contact Sadid Gostaran for a configuration-specific quotation.
Request an NVIDIA H200 NVL Quotation
Ask about the 141GB PCIe accelerator, NVLink bridge configurations, server compatibility, availability, warranty and delivery options.
+98 912 427 1734MESSAGE ON WHATSAPP ↗WhatsApp inquiries only · Sadid GostaranAvailable in Iran
Looking for the NVIDIA H200 NVL 141GB PCIe product page for the Iranian market? Visit the Persian product page for local product information and purchasing options.
View Persian Product PageExplore more: NVIDIA product directory · AI infrastructure in Iran