NVIDIA DGX H200 Price, Technical Specifications & Availability
A procurement-focused guide to NVIDIA DGX H200, an integrated enterprise AI system built for large-scale model training, generative AI, inference and high-performance computing. Explore its eight H200 GPUs, high-bandwidth memory, accelerated networking and deployment requirements.
What Is NVIDIA DGX H200?
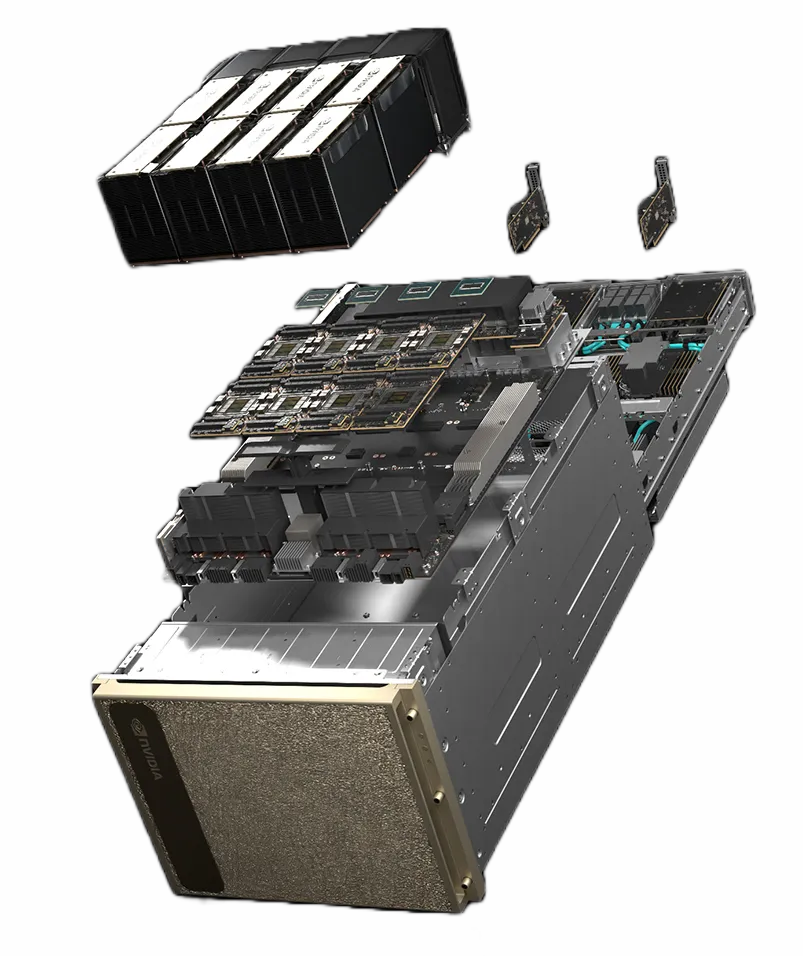
NVIDIA DGX H200 is an integrated AI infrastructure system that combines eight NVIDIA H200 Tensor Core GPUs with high-speed GPU interconnects, dual Intel Xeon processors, high-capacity system memory, enterprise networking and NVMe storage. It is designed to help organizations build and operate large-scale AI environments without assembling every component independently.
The platform is part of the NVIDIA DGX ecosystem and is designed for demanding enterprise AI and high-performance computing workloads, including generative AI, natural language processing and deep learning recommendation systems.
Eight NVIDIA H200 Tensor Core GPUs
At the center of DGX H200 are eight NVIDIA H200 Tensor Core GPUs, each equipped with 141GB of HBM3e memory. Together, the GPUs provide 1,128GB of total GPU memory, enabling the system to address large models and datasets that can be difficult to accommodate on smaller GPU platforms.
NVIDIA specifies up to 32 petaFLOPS of FP8 AI performance for the DGX H200 system. Real-world throughput depends on model architecture, numerical precision, software optimization, parallelism strategy and the workload itself.
NVIDIA DGX H200 Technical Specifications
The following system-level specifications are based on NVIDIA's published DGX H200 datasheet and system documentation.
| System | NVIDIA DGX H200 |
|---|---|
| GPU architecture | NVIDIA Hopper |
| GPU configuration | 8 × NVIDIA H200 Tensor Core GPUs |
| GPU memory | 141GB HBM3e per GPU · 1,128GB total |
| AI performance | 32 PFLOPS FP8 |
| GPU interconnect | NVIDIA NVLink and 4 × NVIDIA NVSwitch |
| GPU-to-GPU bandwidth | Up to 900GB/s |
| CPU | 2 × Intel Xeon Platinum 8480C |
| CPU cores | 112 total · 56 cores per processor |
| System memory | 2TB DDR5 |
| OS storage | 2 × 1.92TB NVMe M.2 SSD |
| Internal data storage | 8 × 3.84TB NVMe U.2 self-encrypting drives |
| Cluster networking | 8 × single-port NVIDIA ConnectX-7 VPI, up to 400Gb/s each |
| Storage and management networking | 2 × dual-port NVIDIA ConnectX-7 VPI, up to 400Gb/s |
| Maximum system power | Approximately 10.2kW |
| Power supplies | 6 × 3.3kW power supply units |
| System management | Host BMC with RJ45; Redfish, IPMI, SNMP, KVM and web interface support |
1,128GB of HBM3e GPU Memory
Each H200 GPU provides 141GB of HBM3e memory. Across all eight GPUs, DGX H200 provides 1,128GB of aggregate GPU memory. This capacity is particularly valuable for large language models, long-context workloads, large batch sizes and AI applications with demanding memory requirements.
The system also includes 2TB of DDR5 system memory, providing host-side capacity for data preparation, orchestration and other CPU-based processes that support GPU workloads.
NVLink, NVSwitch and 400Gb/s Networking
NVIDIA NVLink and NVSwitch provide high-bandwidth communication between the eight GPUs, supporting workloads that distribute model computation and data across multiple accelerators. NVIDIA lists up to 900GB/s GPU-to-GPU bandwidth for DGX H200.
For cluster connectivity, the system uses NVIDIA ConnectX-7 VPI adapters and supports InfiniBand or Ethernet configurations up to 400Gb/s per connection, depending on the selected network mode and deployment design.
GPU Fabric
NVLink and NVSwitch enable high-speed communication between GPUs within the DGX H200 system.
Cluster Fabric
ConnectX-7 networking supports integration into high-performance AI clusters and storage networks.
NVMe Storage and Front-Panel Architecture
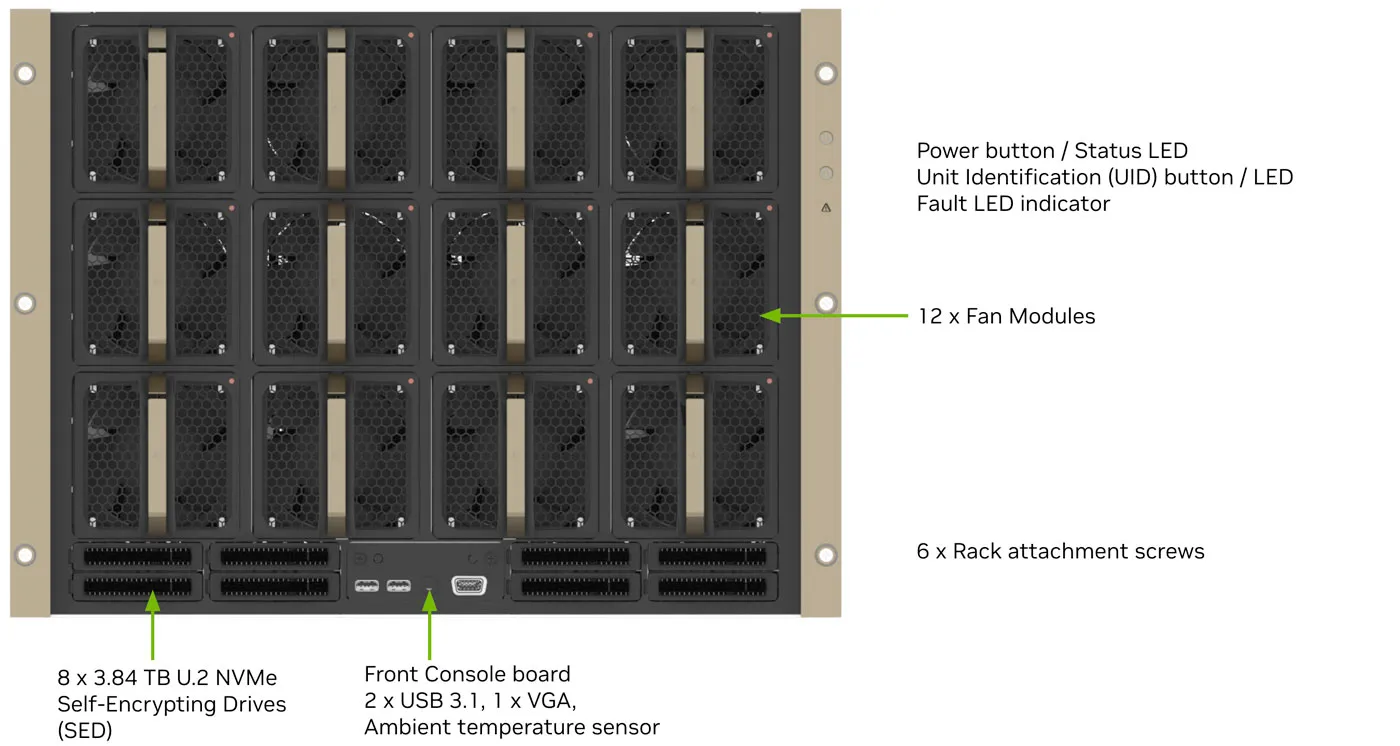
The DGX H200 storage configuration includes two 1.92TB NVMe M.2 drives for the operating system and eight 3.84TB NVMe U.2 self-encrypting drives for internal data cache. The U.2 drives are designed for high-performance local data access in demanding AI workflows.
Front Panel Components
The illustrated front panel identifies 12 fan modules, eight 3.84TB U.2 NVMe self-encrypting drive bays, front console connections and rack attachment points.
Image supplied for product identification and visual reference.
What Can NVIDIA DGX H200 Be Used For?
Large Language Model Training
Train and fine-tune large models using distributed GPU compute and high-capacity HBM3e memory.
Generative AI Inference
Deploy demanding inference workloads and serve AI applications that require substantial GPU memory and throughput.
Natural Language Processing
Support large-scale NLP research, model development and production workloads.
Scientific Computing and HPC
Accelerate compatible simulation, analytics and computational research applications.
Recommendation Systems
Process large-scale deep learning recommendation models and data-intensive training pipelines.
Enterprise AI Platforms
Build centralized AI infrastructure for teams developing and deploying multiple AI services.
Power, Cooling and Deployment Requirements
DGX H200 is a high-density enterprise server with a maximum system power specification of approximately 10.2kW. Deployment planning should account for rack capacity, electrical distribution, cooling, airflow, network fabric, service access and the wider data-center environment.
- Power infrastructure: validate electrical capacity, power distribution units, redundancy and connector requirements.
- Cooling: confirm that the data center can dissipate the system's heat output under sustained workloads.
- Rack integration: verify rack compatibility, mounting, weight limits, cable routing and service clearances.
- Network design: plan InfiniBand or Ethernet topology, switch capacity and storage connectivity.
- Software stack: plan DGX OS, NVIDIA AI Enterprise and the required orchestration and cluster-management components.
NVIDIA DGX H200 Price
The NVIDIA DGX H200 price depends on configuration, regional supply, distributor allocation, support coverage, warranty terms, shipping destination and deployment requirements. Enterprise procurement may also include networking, rack integration, software and support services.
For a relevant quotation, provide the required quantity, destination country, target delivery schedule and any specific support or deployment requirements. Pricing and configuration should be confirmed in a formal quotation rather than assumed from indicative market listings.
DGX H200 Availability and Lead Time
Availability and delivery lead time are confirmed at the time of enquiry. Supply may vary according to system configuration, allocation, region, shipping arrangements and support requirements.
To request an estimate, share your destination, required quantity and target delivery date. Any indicative schedule remains subject to written confirmation and current supply conditions.
Frequently Asked Questions
How many GPUs are included in NVIDIA DGX H200?
The DGX H200 system includes eight NVIDIA H200 Tensor Core GPUs.
How much total GPU memory does DGX H200 provide?
Each H200 GPU has 141GB of HBM3e memory, providing 1,128GB in total across eight GPUs.
What is the AI performance of DGX H200?
NVIDIA specifies up to 32 petaFLOPS of FP8 AI performance for the system. Actual results depend on workload and software configuration.
What processors are used in DGX H200?
The published DGX H200 configuration uses two Intel Xeon Platinum 8480C processors, with 112 CPU cores in total.
What is the maximum power consumption?
NVIDIA lists maximum system power usage of approximately 10.2kW. Facility power and cooling should be planned for the complete deployment.
Does DGX H200 support InfiniBand and Ethernet?
Its ConnectX-7 VPI networking supports InfiniBand and Ethernet configurations, with link speeds up to 400Gb/s depending on configuration.
How can I check DGX H200 price and availability?
Contact Sadid Gostaran with your quantity, destination and delivery requirements to request current commercial information.
Request a Quotation for NVIDIA DGX H200
Contact our team for current pricing, system availability, delivery lead time and enterprise deployment enquiries.
Chat with Sales on WhatsApp ↗WhatsApp: +98 912 427 1734
Available in Iran
Looking for the NVIDIA DGX H200 product page for the Iranian market? Visit the Persian product page for local product information and purchasing options.
View Persian Product PageExplore more: NVIDIA product directory · AI infrastructure in Iran